If you are choosing an AI coding tool for your team, you probably start with a leaderboard. Who scored highest?
Two things published on October 23 suggest that number tells you less than it seems: a research paper on what the tool wrapped around the AI model actually adds, and a popular coding benchmark that just got stricter.
Both point to the same questions. What does a finished task cost, and how sure are we about the score?
The tool around the model mostly changes the bill
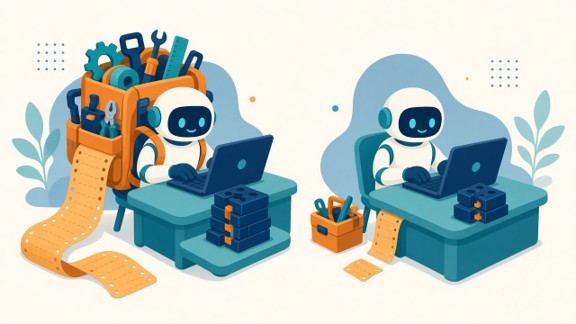
A coding agent is an AI model plus a harness: the system prompt, the tools the model can use, and the rules for managing context. Claude Code and OpenCode are harnesses.
Researchers at Shandong University kept the models fixed and swapped only the harness on tasks from SWE-bench Verified, a common coding benchmark. On 447 tasks, Claude Code and mini-SWE-agent, a minimal harness of about 100 lines of Python, finished within two points of each other. Statistically, a tie. The only clear difference was a loss: OpenCode trailed by up to 9 points, partly because some runs hit an output limit before writing code.
Cost was another story. Same model, same tasks, same prices, and cost per task still varied by up to three times. Much of it comes from the fixed text each harness sends at the start: about 16,600 tokens for Claude Code, 7,000 for OpenCode and 829 for mini-SWE-agent. Agents resend the conversation on every step, so that weight is paid again and again.
A UC Berkeley study, HarnessTax, found the same pattern, with costs up to five times higher.
A two-point lead can be noise
On the 45 hardest tasks, switching harnesses flipped about 13% of problems between pass and fail. Rerunning the same harness flipped the same share.
The paper cites earlier work where ten reruns of one identical setup spread by 2.2 to 6.0 points. So a two or three point gain from a single run should be treated as unproven.
Benchmarks also move. Artificial Analysis released version 2.0 of its Coding Agent Index on October 23, now grading part of the work on whether a maintainer would actually merge the change. The 21 setups measured on both versions fell from an average of 54.8 to 47.4. Last month’s score is not comparable with this month’s.
Ask what a finished task costs
The index also shows cost per task, and the range is wide. According to the launch figures, Claude Code with Claude Opus 5.5 leads at 61.7, at about $11.42 per task in pay-per-token API costs. DeepSeek V4.1 Flash scores 47.3 at about $0.39. Many teams pay by subscription, so read these as relative costs.
Cheaper is not automatically better. For a risky change to a system your business depends on, the stronger setup may be worth it. For small fixes, tests or simple internal tools, maybe not.
Settings matter too. In the Shandong study, a year-old Claude Code release that did not turn on extended thinking by default solved 34 of 45 hard tasks with Claude Opus 5, at about 73 cents per trial at list price. The current release solved 35 to 36, at about $1.65. But switching thinking off hurt some other model and harness pairs badly, so test it rather than guess.
What to do before you pick a coding agent
A leaderboard is a good way to build a short list, not to make the final choice. Before you commit:
- Try two or three options on real tasks from your own codebase.
- Run each more than once before trusting a small difference.
- Track cost per finished task, not just the plan price or the headline score.
- Use a stronger, pricier setup for risky changes and a cheaper one for routine work.
- Test settings like thinking budgets on your own setup before changing them.
The useful number is not who is first. It is what a good, mergeable change costs you, on your code.
How is your team deciding which AI coding tools are worth paying for?
Sources
- VentureBeat: A coding agent’s harness can triple its cost without making it more accurate, study finds (Oct 23, 2026)
- arXiv: What Does a Harness Buy? Tokens, Mostly. (Liu and Han, Shandong University)
- AICoder: Artificial Analysis launches Coding Agent Index v2.0 (Oct 23, 2026)
Artificial Analysis: Coding Agent Benchmarks and Leaderboard